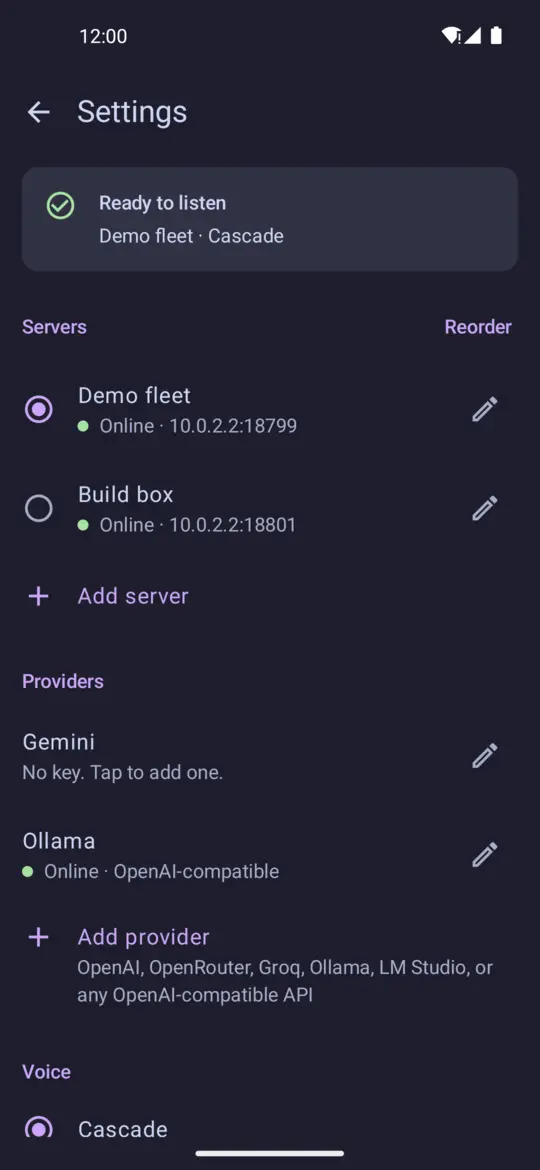
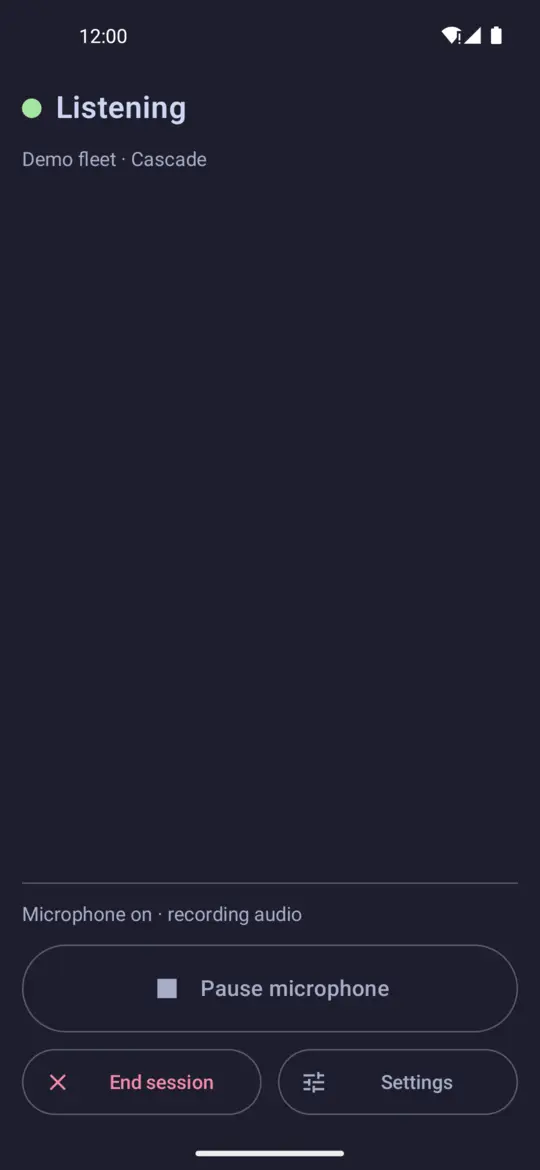
There are two voice engines. Cascade, the default, chains on-device speech recognition, a text model with tool calling and platform text-to-speech; on Gemini that is about 0.05¢ a question. Gemini Live does speech in and out through Gemini; it sounds more natural and costs about 1–1.5¢ a question.
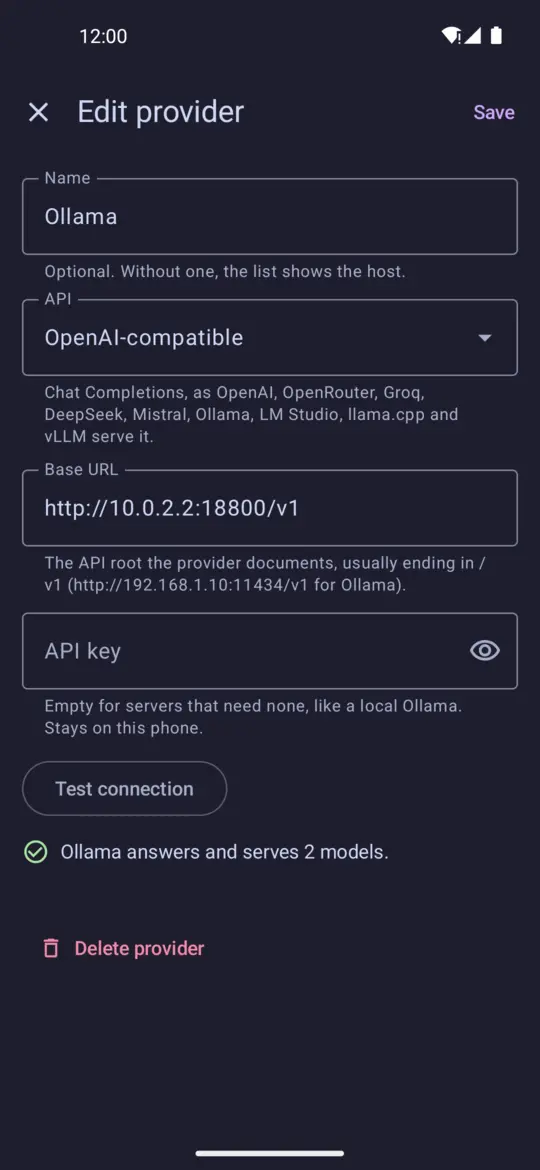
The cascade's text, transcription and summary models can each run on their own provider: any OpenAI-compatible Chat Completions API (OpenAI, OpenRouter, Groq, DeepSeek, Mistral, Ollama, LM Studio, llama.cpp, vLLM) or a Gemini API proxy. A Gemini key is only needed when something actually runs on Gemini.
| Area | Details |
|---|
| Fleet tools | server status, list/search sessions, session details, transcripts, workspaces, usage, live status, follow/unfollow with spoken status changes |
| Hands-free | barge-in, runs with the screen off as a foreground service, idle reset with an optional summary to keep context costs flat |
| Servers | several serve instances, each checked for address and token |
| Costs | per-answer and per-session cost and token counts |
| Desktop | typed questions, mic, or global push-to-talk on Linux |
serve has no TLS; the app allows cleartext HTTP for LAN or Tailscale addresses, and wants a TLS reverse proxy anywhere else.